
AI Note
: no matching posts.
Clear filters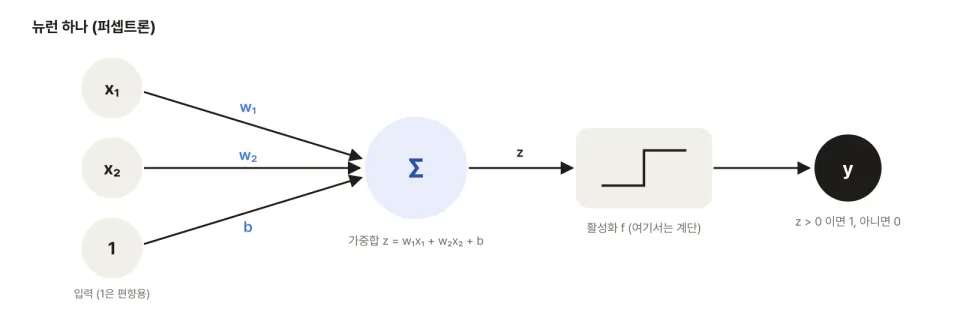
 AI Note
Neural Network Basics: From the Perceptron to Multilayer Networks
Part 1 of AI Note. Starting from a single neuron's weighted sum and activation, we follow why the perceptron cannot solve XOR and how stacking layers solves it, softmax and cross-entropy loss, and gradient descent under different learning rates, all with numeric examples worked out by hand.
 AI Note
Backpropagation: Gradients via the Chain Rule and MNIST in NumPy
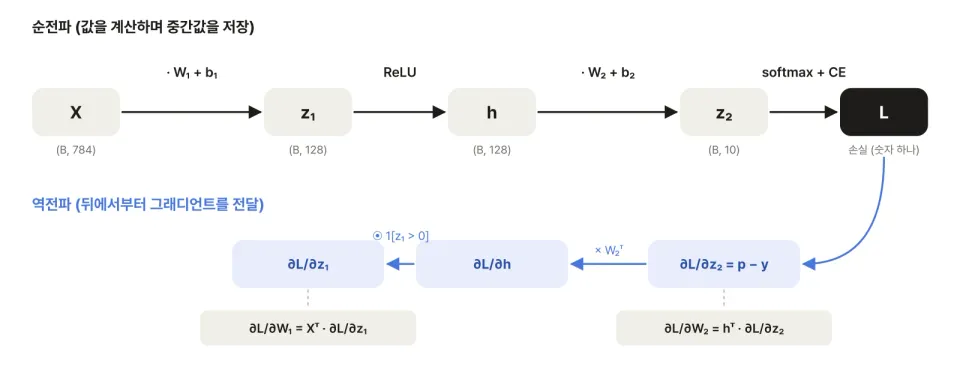
Part 2 of AI Note. We follow backpropagation through the chain rule and computational graphs, starting from numeric examples, derive the gradients of a two-layer network in matrix form, and implement it from scratch in NumPy to reach 97.7% on MNIST. We also measure why minibatches are fast.