Chapter 3: Memory Hierarchy Overview
The memory hierarchy is the key optimization for creating the illusion of a virtual memory with "the speed of the fastest memory + the capacity of the largest memory." It exploits program locality (temporal & spatial) to combine a small, fast memory with a large, slow one.
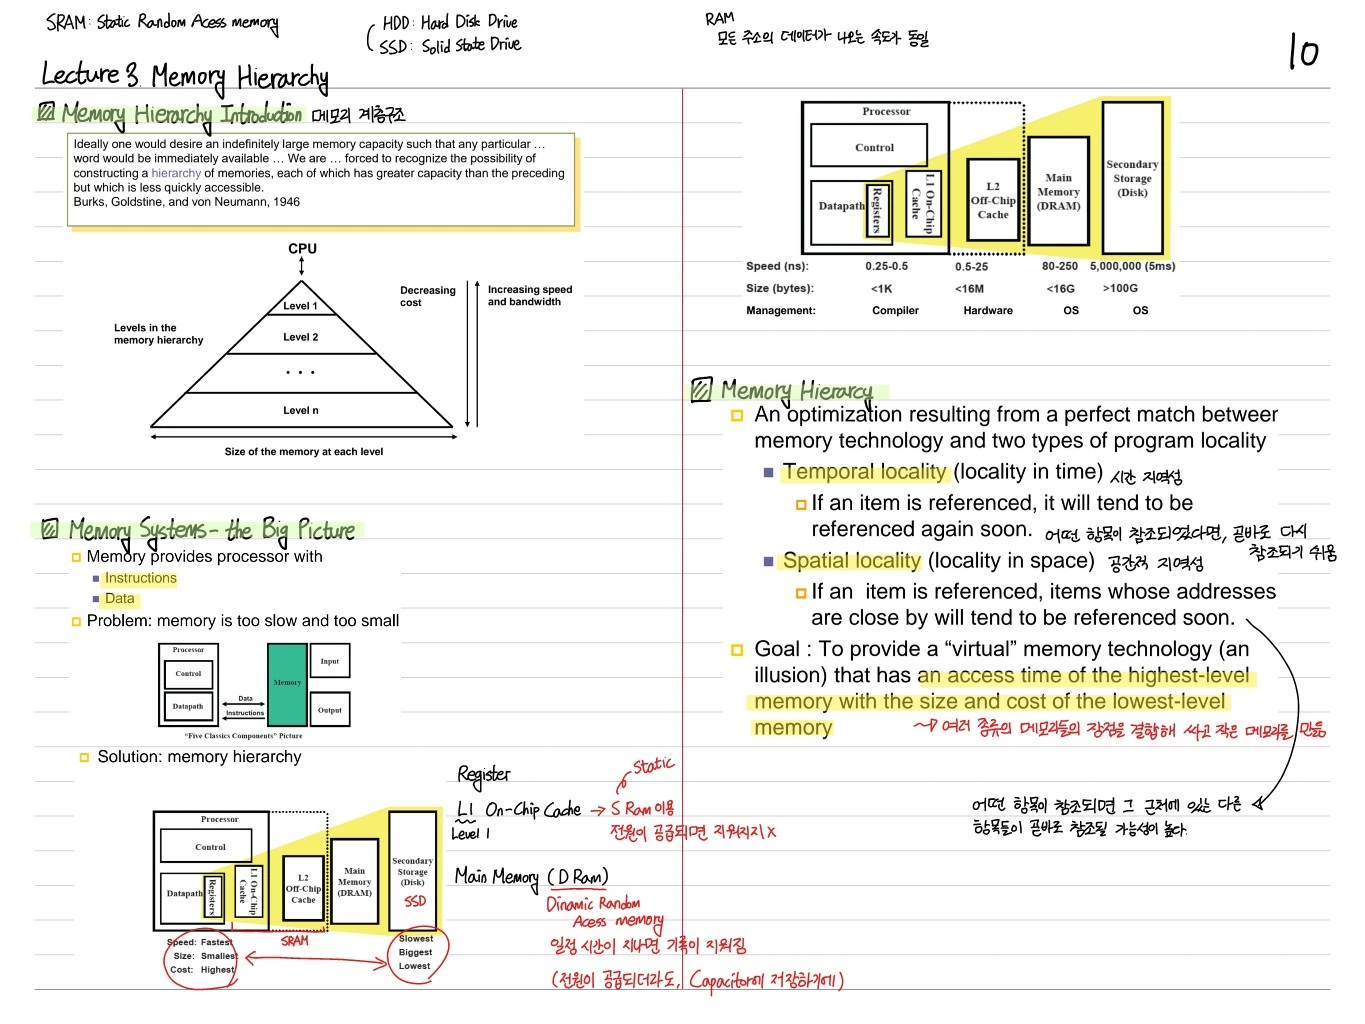
Memory Hierarchy: Solution to Memory Wall
The big picture of the memory system
- Memory: Stores programs and data
- Problem: Memory is too slow and too small compared to CPU
       (fast, small, expensive)
            [ Register ]
              [ L1 $ ]
             [   L2 $   ]
           [  Main memory  ]
         [      Disk       ]
[ Tape (slow, huge, cheap) ]- Speed: sub-ns → ms
- Size: 1 KB → TB
Definition of the memory hierarchy
An optimization resulting from a perfect match between memory technology and two types of program locality.
- Temporal locality: data that has been referenced once is likely to be referenced again soon
- Spatial locality: when one piece of data is accessed, data near it is likely to be referenced soon
Goal: Provide a "virtual" memory technology (illusion) that has an access time of the highest-level memory with the size and cost of the lowest-level memory.
Memory Hierarchy Terminology
- Hit: Accessed data is found in upper level (present in the upper level — success)
- Miss: not in the upper level; must be fetched from the level below
- Hit time: access time of the upper level
- Miss penalty: extra time to fetch from the lower level when a miss occurs
- Hit ratio (Hit rate): , Miss ratio = 1 - Hit ratio
- Average memory access time (AMAT):
L0/L1 Cache Overview
- Upper level: SRAM (fast, expensive)
- Lower level: DRAM (large, slow, cheap)
- Goal: To provide a "virtual" memory technology
- Additional benefits:
- Reduction of memory bandwidth consumed by processor
- More memory bandwidth to I/O
- No need to change the ISA
- To the CPU, it looks like one large memory (illusion)
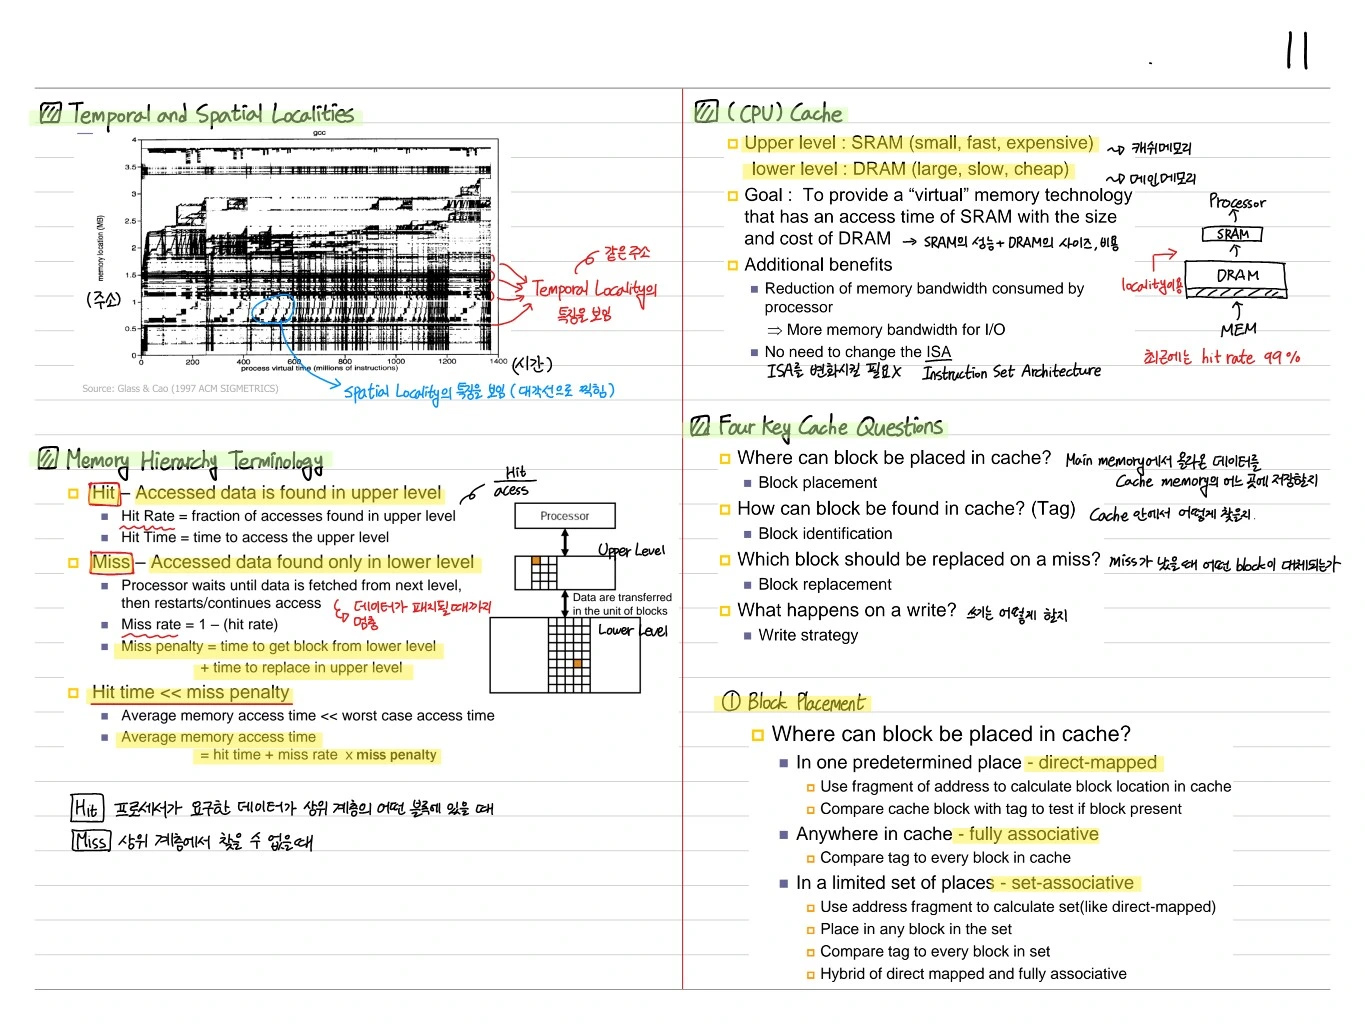
Four Big Cache Questions
- Q1: Where can block be placed in cache? → Block placement
- Q2: How can block be found in cache? → Block identification
- Q3: Which block should be replaced on a miss? → Block replacement
- Q4: What happens on a write? → Write strategy
Block Placement — three schemes
- Direct-mapped: each block can go in only one place in the cache.
- Fully associative: any place is allowed (every slot must be searched)
- Set associative: in between. The cache is divided into sets, and placement within a set is fully associative. N-way set associative.
Direct-Mapped Cache in Detail
- Each memory block is mapped to a single block in cache
- Mapped cache block is determined by memory block address number of blocks in cache
- Cache index: Block # (bit address)
- Comparison: hit/miss is decided by the tag and block number + the valid bit
Block Identification
- Every cache block has an address tag that identifies its location in memory
- Hit when tag and valid bits match + Miss otherwise
- What happens when a cache block is empty? → Mark this condition with a valid bit (0 = empty)
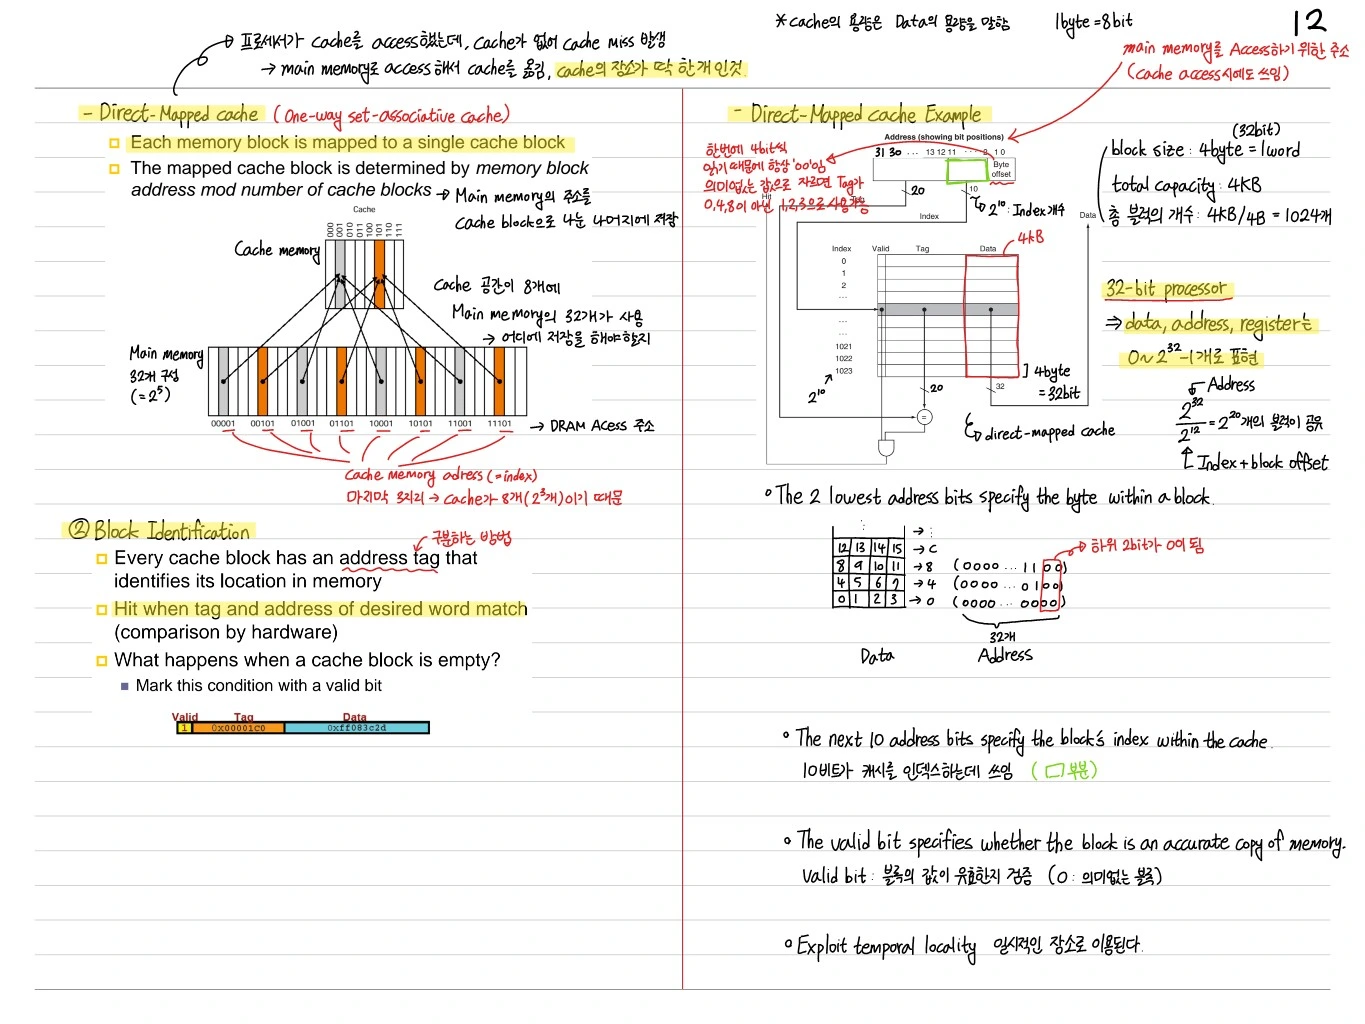
Direct-Mapped Cache Example
16B block, 8 cache blocks, 5-bit index, 3-bit offset. Access the cache block index from the memory address → compare the tag → decide hit/miss.
Step by step:
- Address decoding:
[tag | index | offset] - Block address = Memory address / Block size
- Cache index = Block address mod Cache blocks
- The miss ratio depends on temporal/spatial locality
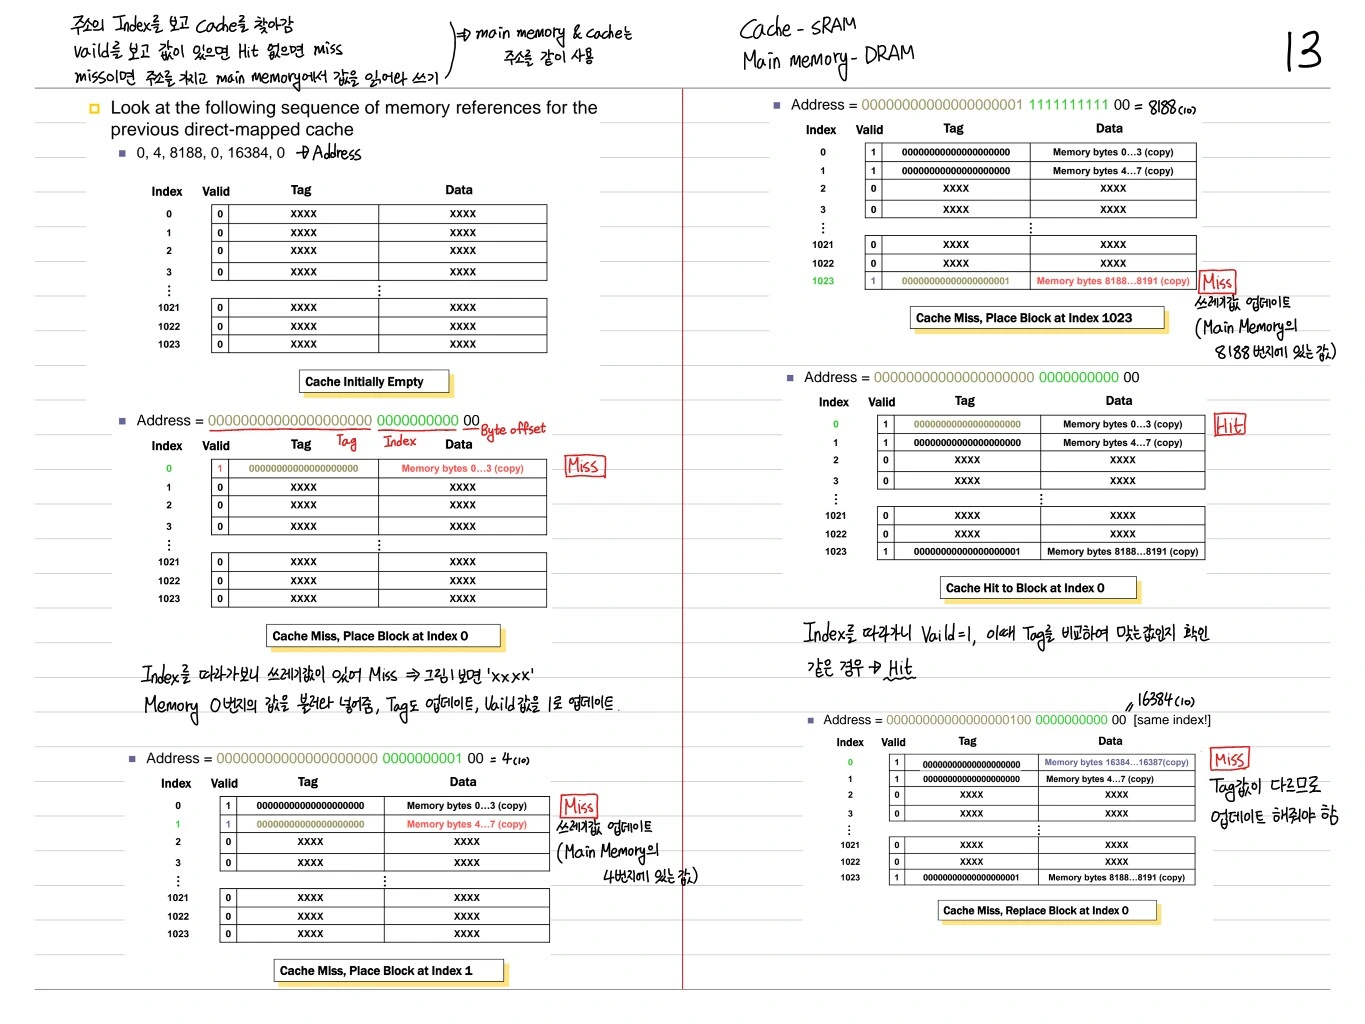
Block Size Considerations
- Larger blocks: less use of spatial locality, but higher latency
- But in a fixed-size cache:
- Larger blocks → fewer of them → more competition → higher miss rate
- Larger blocks → pollution (data that is never used enters the cache)
- Larger miss penalty → can override benefit of reduced miss rate
- Early restart and critical-word-first can help
Miss rate vs Block size
- Too small, and spatial locality is underused
- Too large, and the cache gets polluted + the miss penalty grows
- A middle value is optimal (typically 32–128B)
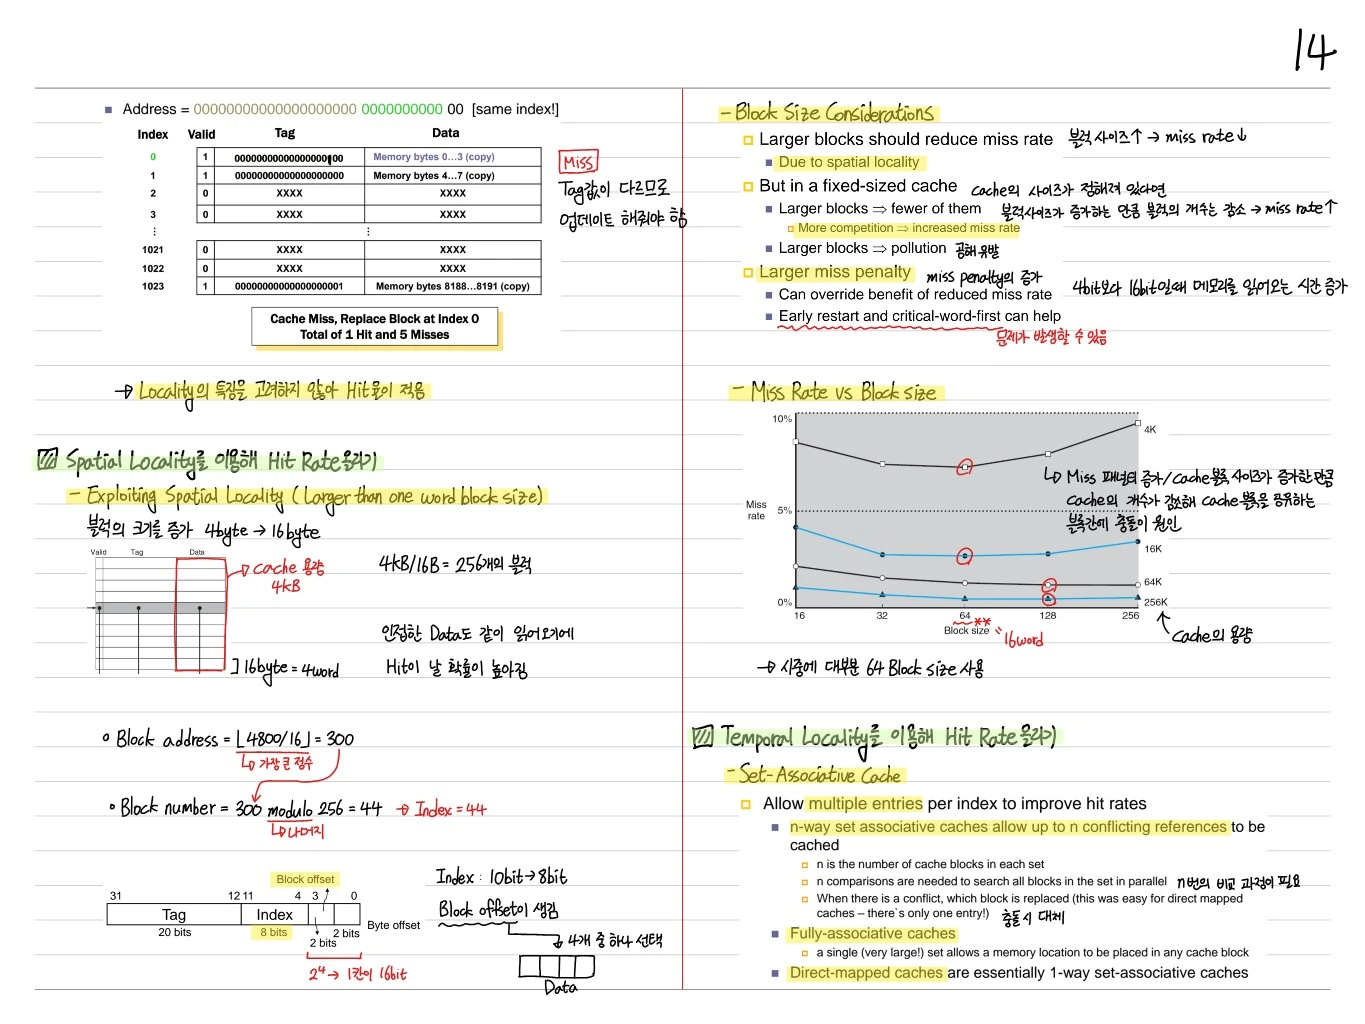
Cache Organization Spectrum
Direct-mapped vs Fully associative vs Set-associative
- Set-associative cache: fully associative within a predetermined set
- Four-way set associative: 4 sets × N blocks
- For fixed cache capacity, higher associativity tends to higher hit rate
Set-Associative Cache Organization
- Index → select a set → compare tags within the set (fully associative)
- For 4-way, the same index compares 4 tags in parallel
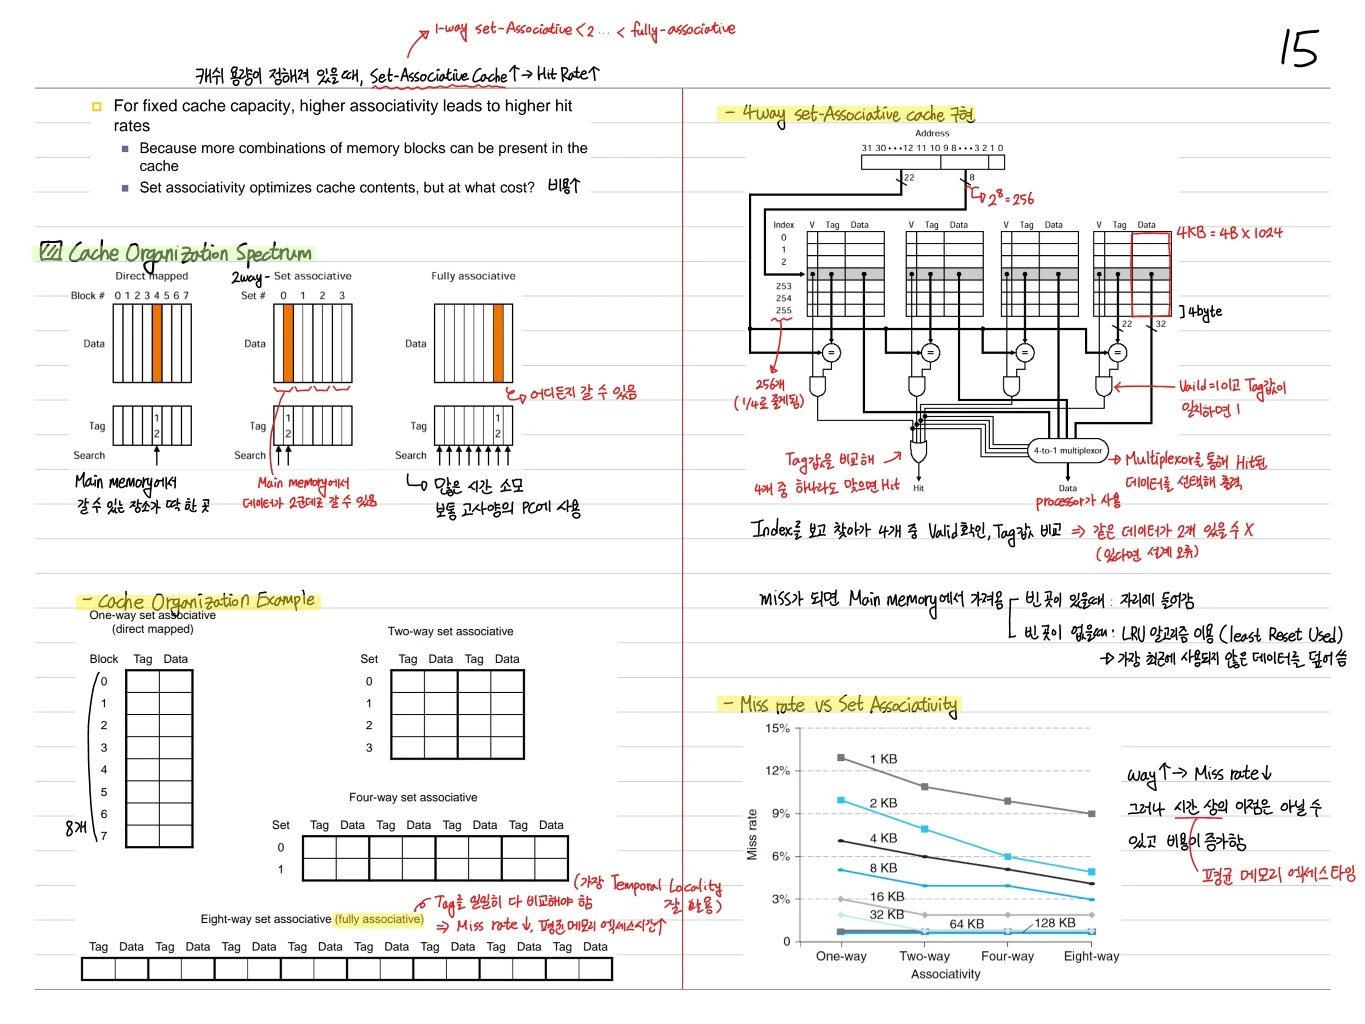
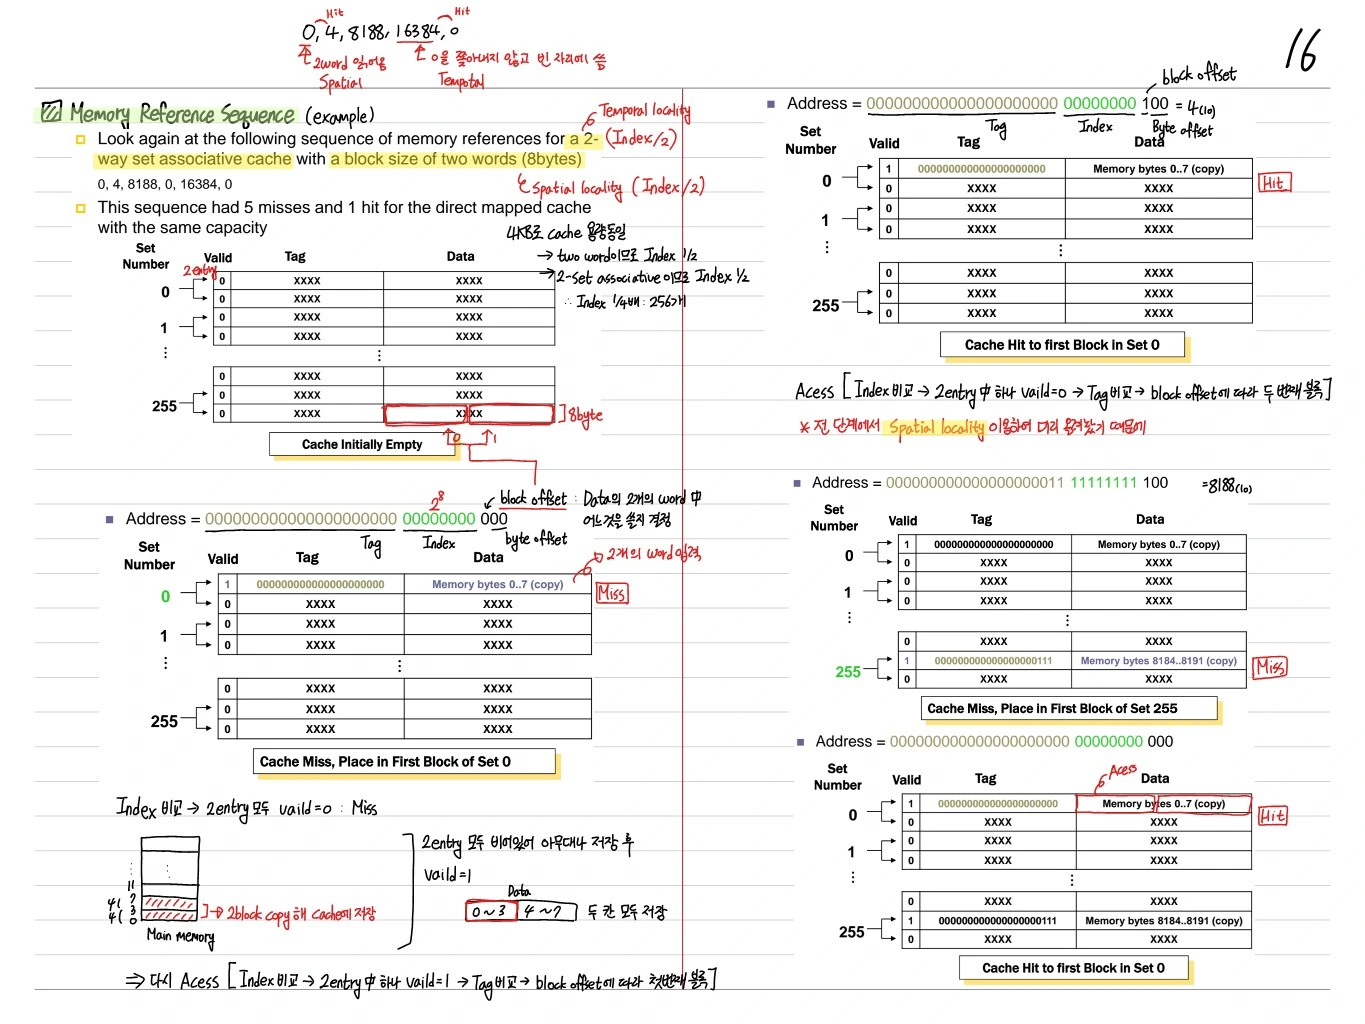
Memory Reference Sequence Example
Cache initially empty, 1 hit for the third memory reference with the same capacity.
Trace the access pattern step by step and compare the hit/miss counts for each cache. The set-associative cache gets more hits than the direct-mapped one.
Cache Read Operation
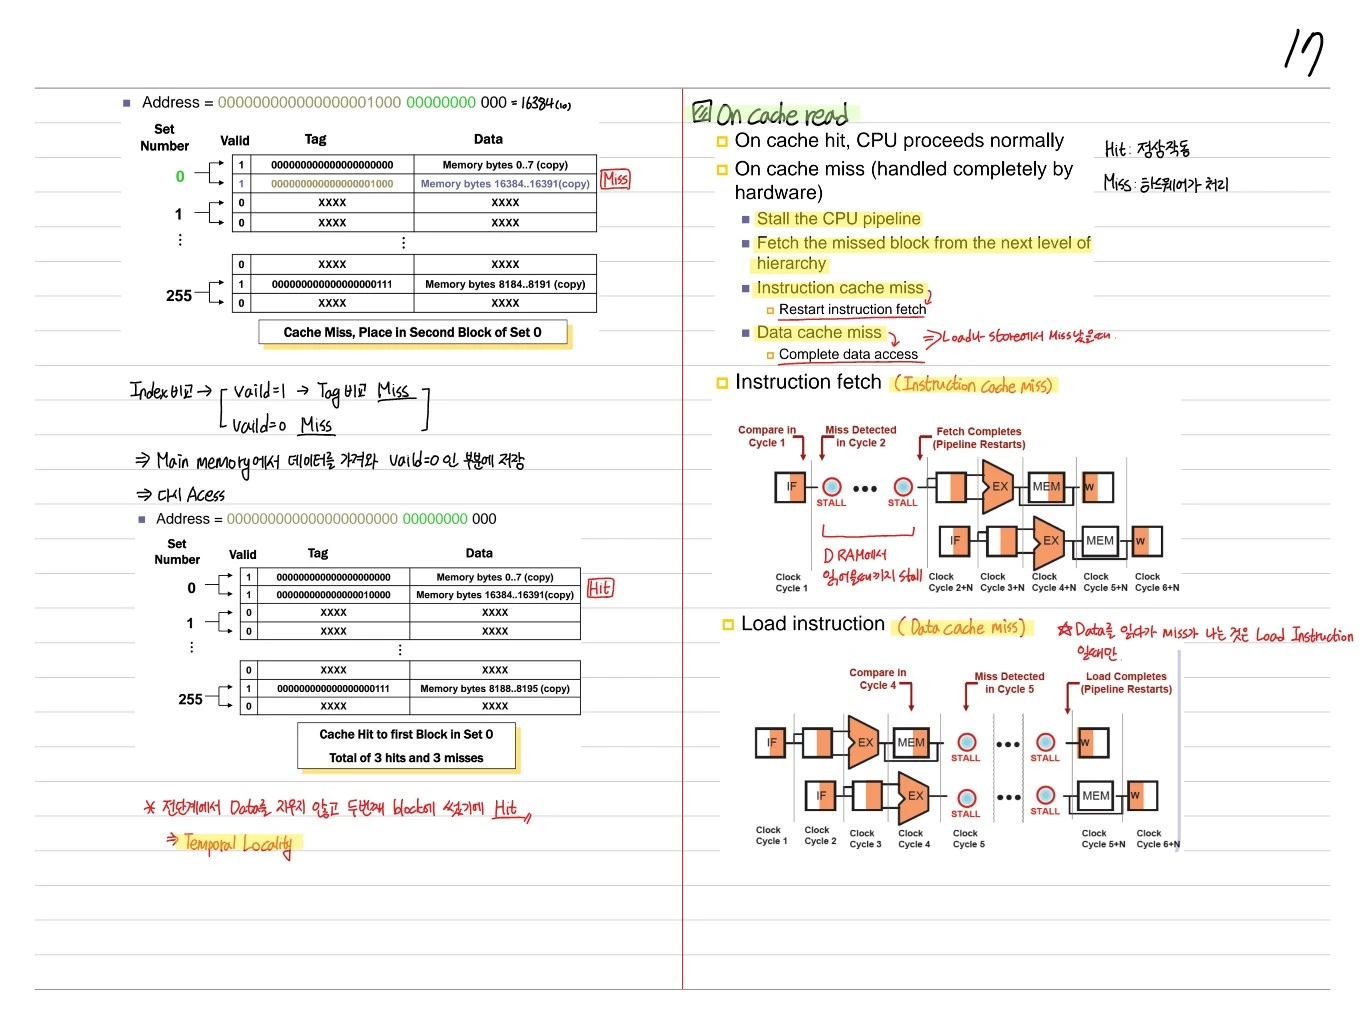
On cache hit
CPU proceeds normally — normal operation.
On cache miss (handled completely by hardware)
- Stall the CPU pipeline
- Fetch the missed block from the next level of hierarchy
- Instruction cache miss → Restart instruction fetch
- Data cache miss → Complete data access
Instruction Fetch Flow (Instruction Cache Miss)
Compare in clock cycle 1, miss detected in cycle 2 → stall → fetch completes → pipeline restart. The pipeline stalls until the data is read from DRAM.
Load Instruction Flow (Data Cache Miss)
A miss while reading data only happens on a load instruction. Compare in cycle 4, miss detected in cycle 5 → stall → load completes → pipeline restart.
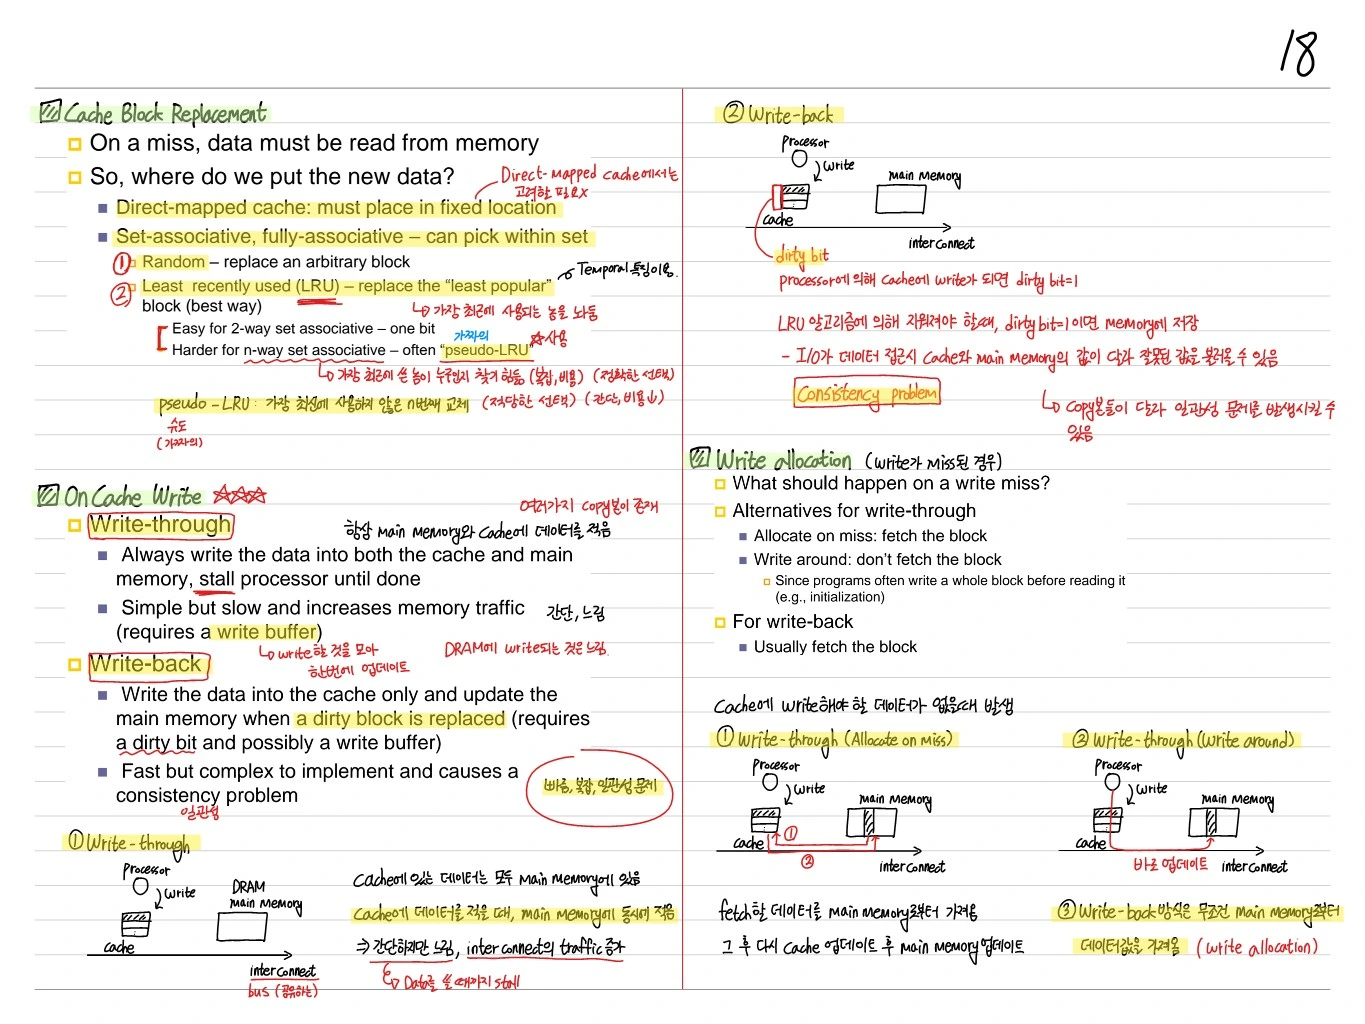
Cache Write Strategies
Write-Through
- Always write the data into both the cache and main memory
- Simple but slow — increases memory traffic
- Needs a write buffer (makes main memory writes asynchronous)
Write-Back
- Write the data into the cache only
- Update the main memory when a dirty block is replaced
- Requires a dirty bit (marks whether the block was modified)
- Fast but complex to implement and causes a consistency problem
Write Miss Handling
- Write-allocate: on a miss, bring the block into the cache and then write
- No-write-allocate: on a miss, write directly to memory only (the cache is untouched)
Write-back is usually paired with write-allocate, and write-through with no-write-allocate.
Cache Performance
AMAT
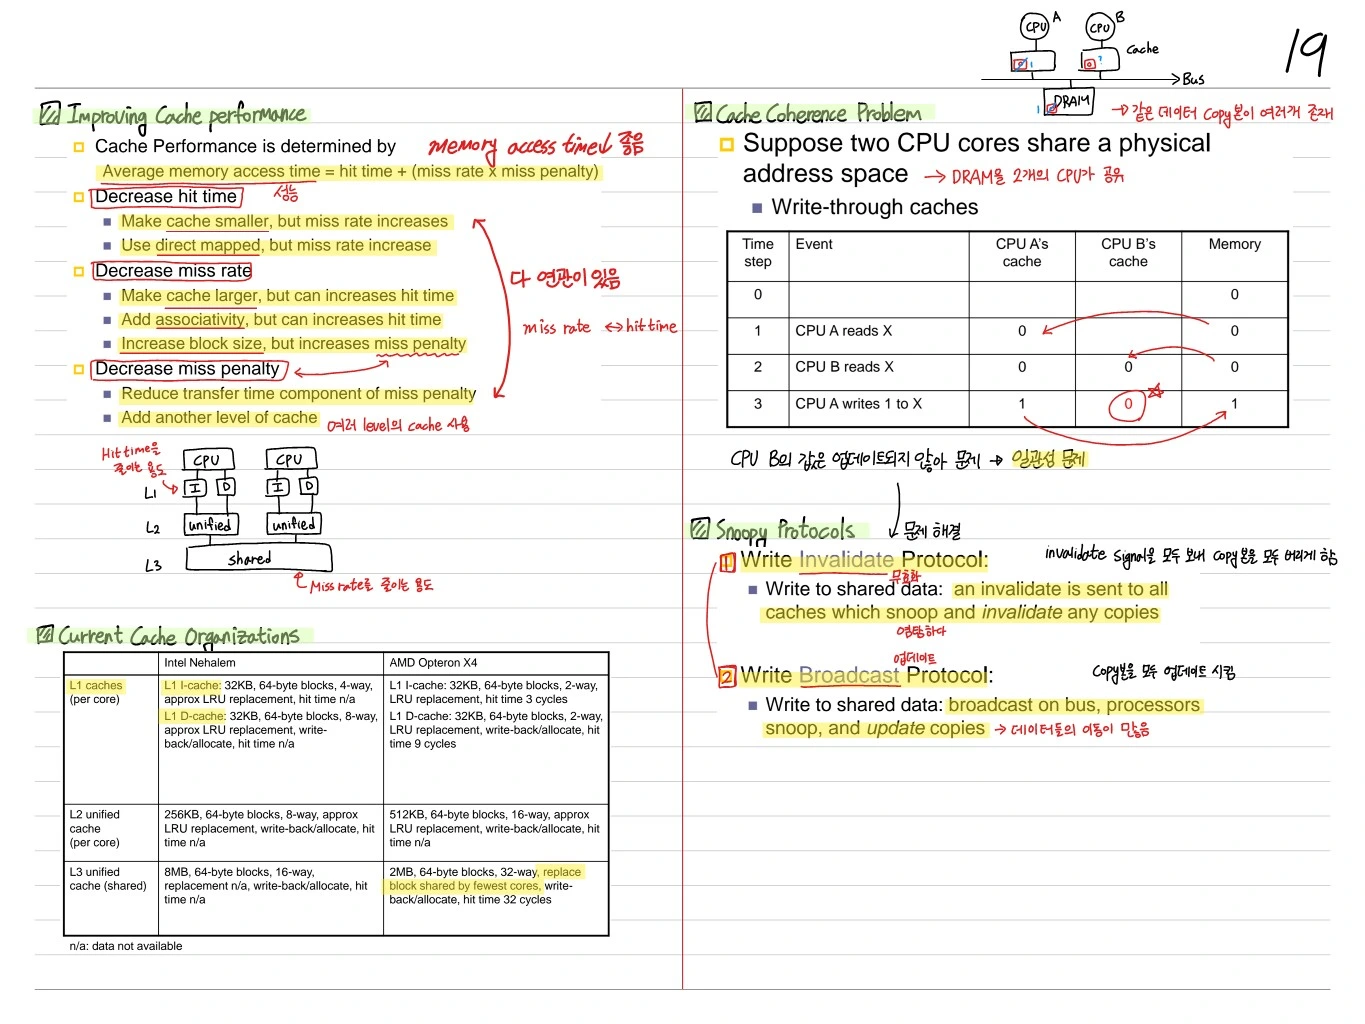
Improving Cache Performance
- Decrease hit time: Small & direct-mapped cache
- Decrease miss rate: Bigger cache, more associativity
- Decrease miss penalty: Multi-level cache, critical-word first, prefetching
Current Cache Organizations
| Level | Cache size | Access time | Associativity |
|---|---|---|---|
| L1 D-cache | 32 KB | 1 cycle | 4-way |
| L1 I-cache | 32 KB | 1 cycle | 4-way |
| L2 | 256 KB | 10 cycles | 8-way |
| L3 | 8 MB | 30 cycles | 16-way |
| Main memory | GB | 100+ cycles | - |
Cache Coherence Problem
Suppose two CPU cores share a physical address space.
Example with write-through caches:
| Time step | Event | CPU A's cache | CPU B's cache | Memory |
|---|---|---|---|---|
| 0 | - | - | - | 0 |
| 1 | CPU A reads X | 0 | - | 0 |
| 2 | CPU A writes 1 to X | 1 | - | 1 |
| 3 | CPU B reads X | 1 | 0 | 1 |
→ CPU B's cache is stale (0) → coherence problem.
Snoopy Protocol
- Write-Broadcast: Write to shared data → an invalidate is sent to all other caches
- Write-Invalidate: Write to shared data → broadcast on bus, processors snoop and update copies
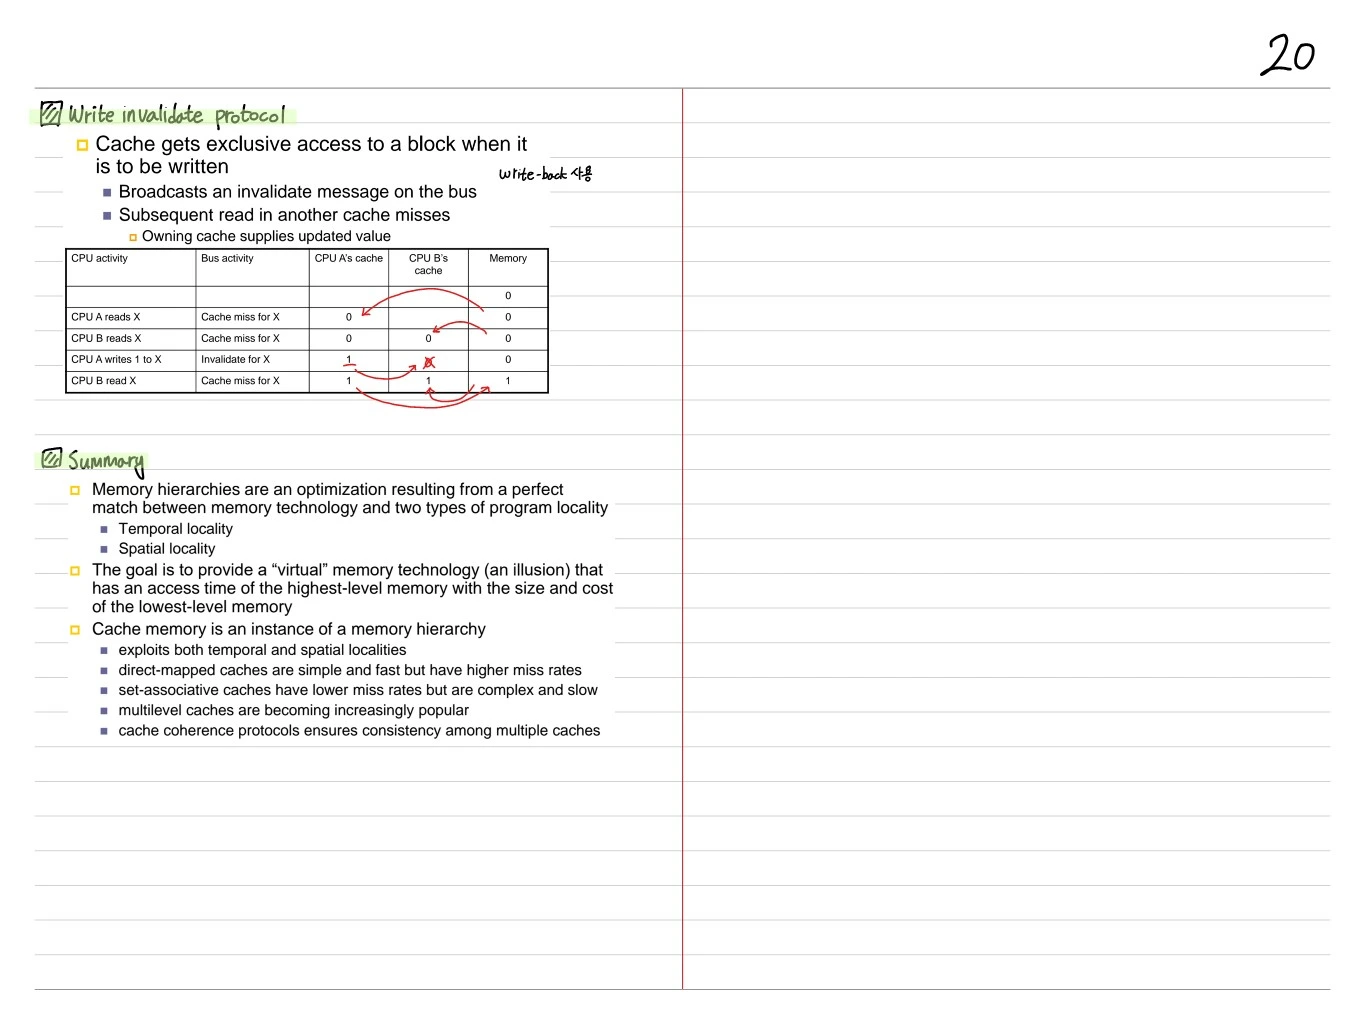
Write Invalidate Protocol in Detail
Cache gets exclusive access to a block when it is to be written:
- Broadcasts an invalidate message on the bus
- Subsequent read in another cache misses → Owning cache supplies updated value
Example scenario (using write-back):
| CPU activity | Bus activity | CPU A's cache | CPU B's cache | Memory |
|---|---|---|---|---|
| - | - | - | - | 0 |
| CPU A reads X | Cache miss for X | 0 | - | 0 |
| CPU B reads X | Cache miss for X | 0 | 0 | 0 |
| CPU A writes 1 to X | Invalidate for X | 1 | X (invalid) | 0 |
| CPU B reads X | Cache miss for X | 1 | 1 | 1 |
→ The owning cache (A) supplies the latest value.
Summary
- Memory hierarchies are an optimization resulting from a perfect match between memory technology and two types of program locality
- Temporal locality / Spatial locality
- The goal is to provide a "virtual" memory technology (illusion) that has an access time of the highest-level memory with the size and cost of the lowest-level memory
- Cache memory is an instance of a memory hierarchy
- Exploits both temporal and spatial localities
- Direct-mapped caches are simple and fast but have higher miss rates
- Set-associative caches have lower miss rates but are complex and slow
- Multilevel caches are becoming increasingly popular
- Cache coherence protocols ensure consistency among multiple caches